Bookumi
TLDR
This project was created as my bachelor's final project. I built it to answer a question I had after seeing many recommender system research papers. Most of them focus on improving recommendation algorithms, but very few explain how to integrate those algorithms into a real application so that end users can actually use them easily.
For this project, I chose the book domain because books are popular among people in my city, and the reading rate has been increasing in recent years . The dataset used in this project is the Goodreads dataset, which was crawled and published by researchers from the University of California, San Diego. It is publicly available at Goodreads Datasets . For this project, I used a subset of the book dataset consisting of comic books. This subset was selected because it is the smallest category in the dataset, making it suitable for prototyping and reducing computational requirements during development.
I use Hybrid Recommender System with "Switching Hybrid Approach" method. The method will use content-based filtering method if the user hasn't rated any books yet. Otherwise, it will use the collaborative filtering method.
In this project, I do not focus on optimizing the recommendation algorithms. Instead, I focus on the implementation strategy and the user experience.
Mapping Website Page and Feature for Planning Model Implementation
I use some website with same feature as inpiration to plan how can I implement the recommender model. The website are Goodreads, Amazon, Gramedia, and etc. When I take look in those website, every website have similiar "pattern" for navigate user from page to page. Start with homepage with a list of book item, the book item detail, and the book that related with the book detail.
If you take a closer look, the content-based filtering method can be implemented on the book detail page. The description of the selected book can be used as the query to find similar books based on their content. This improves the user experience by helping users discover new books that are similar to the one they are currently interested in.
To implement the collaborative filtering method, user interaction data is required. In this project, users can rate books, and those ratings are used to generate recommendations based on the preferences of other users with similar interests.
If I break down that thinking to a simple list what should I create, here the list:
Content-Based Filtering
- Retrieve the details of the selected book.
- Use the book's description as the input to identify books with similar content.
- Display the recommended books on the book detail page to help users discover titles related to their current interest.
Collaborative Filtering
- Allow users to create an account and sign in before submitting ratings.
- Collect each user's book rating history as interaction data.
- Generate personalized book recommendations based on the preferences of users with similar rating patterns.
Model Preparations
Since the primary focus of this project is not on the model-building process, I will skip the training details and move directly to model preparation. In this context, model preparation refers to converting the trained models into a format that can be efficiently loaded and used by the backend application.
Content-Based Filtering Model
I will briefly explain the approach I used to train the recommendation models. For the content-based filtering model, I used TfidfVectorizer from sklearn.feature_extraction.text to generate TF-IDF vectors from the book descriptions. TF-IDF is a text representation technique that measures the importance of words within a document, making it effective for comparing the similarity between textual content.
After generating the TF-IDF vectors, I indexed them using FAISS, which serves as a vector similarity search library. FAISS enables efficient nearest-neighbor searches over high-dimensional vectors and implements optimized indexing algorithms that significantly improve search performance compared to a brute-force approach.
The output of this process consists of two files that are required during inference. The first is faiss_book_recommender.index, which stores the FAISS vector index, and the second is book_mappings.pkl, which stores the mapping between the FAISS index and the corresponding book IDs. Saving these files allows the backend to load the trained model and efficiently retrieve the correct book information during recommendation.
Collaborative Filtering Model.
The collaborative filtering model is more straightforward. Since I used the SVD algorithm to build the model, the trained model can be serialized and saved as a .pkl file. This file can then be loaded by the backend to generate recommendations based on the preferences and ratings of similar users.
Model Implementation
Model Loading In Backend Service
The trained models and indexes are loaded by the backend service during application startup. For the backend implementation, I used FastAPI because it is built on the same Python ecosystem that I used for model development. This allows the trained models to be integrated and served efficiently without requiring additional conversion or compatibility layers.
app/recommenders/faiss.py
import faiss
import numpy as np
import pickle

faiss_index_en: faiss.IndexFlatL2 = None
book_id_to_idx_en: dict[int, int] = {}
idx_to_book_id_en: dict[int, int] = {}

faiss_index_ind: faiss.IndexFlatL2 = None
book_id_to_idx_ind: dict[int, int] = {}
idx_to_book_id_ind: dict[int, int] = {}

def load_index(index_path_ind: str, mapping_path_ind: str):
    global idx_to_book_id_en, faiss_index_ind, book_id_to_idx_ind, idx_to_book_id_ind

    faiss_index_ind = faiss.read_index(index_path_ind)

    with open(mapping_path_ind, "rb") as f:
        mappings = pickle.load(f)
        book_id_to_idx_ind = mappings["book_id_to_idx_ind"]
        idx_to_book_id_ind = mappings["idx_to_book_id_ind"]

    print(f"✅ Loaded ID FAISS index with {faiss_index_ind.ntotal} vectors")
    print(f"✅ Loaded {len(book_id_to_idx_ind)} book_id_to_idx mappings")
print(f"🔹 First 5 ID book_ids: {list(book_id_to_idx_ind.keys())[:5]}")app/recommenders/cf_svd.py
from surprise import SVD
from typing import Optional
import pickle

svd_model: Optional[SVD] = None
user_items: Optional[dict[int, list[int]]] = None

def load_svd_and_user_items_dict(file_path: str):
  global svd_model, user_items

  with open(file_path, "rb") as f:
    data = pickle.load(f)

  svd_model = data["model"]
  user_items = data["train_user_items"]

  print("✅ Loaded SVD model and user-item mappings")
  print(f"Total users in training data: {len(user_items)}")
  if len(user_items) > 0:
        example_user = list(user_items.keys())[100]
        print(f"Example user: {example_user}, liked books: {user_items[example_user][:5]}")

def get_similiar_user(liked_books: list[int]) -> Optional[int]:
  if not user_items:
      return None

  best_user = None
  best_overlap = 0

  for uid, books in user_items.items():
     overlap = len(set(books) & set(liked_books))
     if overlap > best_overlap:
        best_overlap = overlap
        best_user = uid

return best_user After implementing the functions to load the FAISS index and the SVD model, they are called from main.py during application startup and their instances are stored in global variables. This ensures that the models are loaded only once when the service starts, eliminating the need to reload them for every incoming request.
app/main.py
from fastapi import FastAPI
from app.routers import book, auth, users, genre, author
from app import models
from fastapi.middleware.cors import CORSMiddleware
from app.database import engine, Base
from app.recommenders.faiss import load_index
from app.recommenders.cf_svd import load_svd_and_user_items_dict
import os
from dotenv import load_dotenv

load_dotenv()

Base.metadata.create_all(bind=engine)

app = FastAPI(title="recommender-service")

app.add_middleware(
    CORSMiddleware,
    allow_origins=[
        "http://localhost:3000",
        "http://localhost:3001",
        "http://127.0.0.1:3000",
    ],
    allow_credentials=True,
    allow_methods=["*"],
    allow_headers=["*"],
)

app.include_router(book.router)
app.include_router(auth.router)
app.include_router(users.router)
app.include_router(genre.router)
app.include_router(author.router)

@app.on_event("startup")
def startup_event():
    load_index(
        os.getenv("PATH_TO_FAISS_INDEX_IND"),
        os.getenv("PATH_TO_FAISS_ID_MAPPING_IND")
    )

    load_svd_and_user_items_dict(
        os.getenv("PATH_TO_SVD_MODEL"),
    )

@app.get("/")
def root():
    return {"message": "FastAPI service is running"}
As shown in the startup_event() function, the model-loading functions are executed during the application's startup phase, ensuring that both the FAISS index and the SVD model are ready to serve recommendations before the API begins handling requests.
Design And Create Recommender Endpoint
After the models have been successfully loaded, the next step is to design the API endpoints so that the frontend application can consume them and display the recommendation results to users.
Content-Based Filtering Recommender
The first endpoint implements the content-based filtering recommender. Its implementation is relatively straightforward. The endpoint requires the book ID to retrieve books with the most similar descriptions. Since I created two separate FAISS indexes and their corresponding index mappings to support both English and Indonesian books, the book's language must also be provided as a parameter so the correct index can be used.
Additional optional parameters include top_k, which specifies the number of similar books to return, and genres, which allows the recommendations to be filtered by one or more genres. The complete implementation of the endpoint is shown below.
app/schema/book.py
class SimiliarBookFilter(BaseModel):
  book_id: int = Field(..., description="book_id")
  book_language_code: str = Field(..., description="book language code")
  top_k: int = Field(5, description="number of total similiar books to return")
  genres: Optional[list[str]] = Field([], description="filter by its genres")
  language_codes: Optional[list[str]] = Field([], description="filter by its language code")

  @classmethod
  def as_query(
    cls,
    book_id: int = Query(...),
    book_language_code: str = Query(...),
    top_k: int = Query(5),
    genres: list[str] = Query(default_factory=list),
    language_codes: list[str] = Query(default_factory=list)
  ):
    return cls(
      book_id=book_id,
      book_language_code=book_language_code,
      top_k=top_k,
      genres=genres,
      language_codes=language_codes
)app/routers/book.py
class SimiliarBookFilter(BaseModel):
@router.get("/similiar", response_model=BaseResponse[PaginatedResponse[BookResponse]])
def get_similiar_books(
  book_filter: SimiliarBookFilter = Depends(SimiliarBookFilter.as_query),
  pagination: Pagination = Depends(),
  db: Session = Depends(get_db)
):
  books, total = BookService.get_similiar_books(
    book_filter,
    pagination,
    db,
  )

  return BaseResponse(
    message=f"Successfully retrieved similar books for book_id {book_filter.book_id}",
    data=PaginatedResponse(
      total=total,
      page=pagination.page,
      limit=pagination.limit,
      items=books
    )
)app/services/book.py
def get_similiar_books(
  book_filter: SimiliarBookFilter,
  pagination: Pagination,
  db: Session
):
  similar_book_ids = []

  if book_filter.book_language_code == "ind":
    # Membuat vector untuk buku yang dicari
    book_idx = FAISSRecommender.book_id_to_idx_ind.get(book_filter.book_id)
    if book_idx is None:
        raise HTTPException(
          status_code=status.HTTP_404_NOT_FOUND,
          detail="Book ID not found in FAISS index"
        )

    book_vector = FAISSRecommender.faiss_index_ind.reconstruct(book_idx)

    # Mencari item dengan jarak vector terdekat
    distances, indices = FAISSRecommender.faiss_index_ind.search(
      book_vector.reshape(1, -1),
      book_filter.top_k + 1
    )
    indices = indices.flatten().tolist()

    # remove itself
    indices = [i for i in indices if i != book_idx]

    similar_book_ids = [FAISSRecommender.idx_to_book_id_ind[i] for i in indices]
  elif book_filter.book_language_code == "en":
    # Membuat vector untuk buku yang dicari
    book_idx = FAISSRecommender.book_id_to_idx_en.get(book_filter.book_id)
    if book_idx is None:
        raise HTTPException(
          status_code=status.HTTP_404_NOT_FOUND,
          detail="Book ID not found in FAISS index"
        )

    book_vector = FAISSRecommender.faiss_index_en.reconstruct(book_idx)

    # Mencari item dengan jarak vector terdekat
    distances, indices = FAISSRecommender.faiss_index_en.search(
      book_vector.reshape(1, -1),
      book_filter.top_k + 1
    )
    indices = indices.flatten().tolist()

    # remove itself
    indices = [i for i in indices if i != book_idx]

    similar_book_ids = [FAISSRecommender.idx_to_book_id_en[i] for i in indices]
  else:
     raise HTTPException(
      status_code=status.HTTP_400_BAD_REQUEST,
      detail=f"unrecognise book_language_code value: {book_filter.book_language_code}"
    )


  books, total = BookCRUD.get_similiar_books(
    book_filter,
    pagination,
    similar_book_ids,
    db,
  )

return books, totalAs shown in the implementation, the book_language_code parameter is used to determine which FAISS index and index mapping should be used. Separate indexes are maintained because the preprocessing pipeline differs between English and Indonesian books, resulting in different vector representations.
The recommendation process consists of the following steps:
- The book ID is used to look up its corresponding vector index in the appropriate FAISS index mapping.
- Once the vector index is found, the associated vector is reconstructed and used as the query for FAISS's
search()function to retrieve the nearest vectors based on similarity. - The returned vector indices are then mapped back to their corresponding book IDs using the index mapping.
- Finally, the list of book IDs is passed to the
get_similiar_books()function, which retrieves the complete book information from the database and returns it to the client.
Collaborative Filtering Recommender
The collaborative filtering recommender is more complex than the content-based filtering endpoint because it relies on each user's book preferences. To support this, the system requires user authentication and a mechanism for users to rate or like books. However, the implementation details of these features are outside the scope of this post.
The recommendation process is implemented as follows:
- Retrieve the list of books that the user has liked.
- Use this information as input to the trained SVD model to generate personalized recommendations.
- Use the recommended book IDs returned by the model to retrieve the complete book information from the database.
If the user has not liked any books, the system does not generate any recommendations and returns an empty result.
app/routers/book.py
@router.get("/similiar/cf-svd", response_model=BaseResponse[PaginatedResponse[BookResponse]])
def get_cf_svd_recommendation(
  pagination: Pagination = Depends(),
  db: Session = Depends(get_db),
  current_user: JWTPayload = Depends(verify_auth_token)
):
  request_with_user: GetCFSVDRecommendation = {
    "user_id": current_user.sub,
    "liked_books": []
  }

  books, total = BookService.get_cf_svd_recommendation(request_with_user, pagination, db)

  return BaseResponse(
  	message=f"success get recommended books for user with id {current_user.sub}",
  	data=PaginatedResponse(
  	  total=total,
  	  page=pagination.page,
  	  limit=pagination.limit,
  	  items=books
  	)
)As shown in the implementation, the function uses the current_user parameter, which is extracted from the JWTPayload and represents the currently authenticated user. The user's ID is then used to construct a GetCFSVDRecommendation request, which is passed to the recommendation service to generate a personalized list of recommended books.
app/services/book.py
def get_cf_svd_recommendation(
  get_recommendation_request: GetCFSVDRecommendation,
  pagination: Pagination,
  db: Session
):
  target_user: list[int]

  if SVDRecommender.svd_model is None or SVDRecommender.user_items is None:
    raise HTTPException(
      status_code=status.HTTP_500_INTERNAL_SERVER_ERROR,
      detail="SVD model and user_items dict not load properly"
    )

  # Get list data buku yang disukai oleh user
  liked_book_ids = BookCRUD.get_liked_book_ids_by_user_id(
    get_recommendation_request["user_id"],
    db
  )

  # Case pertama, jika user_id ada di dalam user_items
  if get_recommendation_request["user_id"] in SVDRecommender.user_items:
    target_user = get_recommendation_request["user_id"]
  else:
    # Case kedua, jika tidak ada user_id di dalam user_items
    if not liked_book_ids:
        raise HTTPException(
          status_code=status.HTTP_400_BAD_REQUEST,
          detail="liked books is required for new users"
        )

    user_with_same_liked = SVDRecommender.get_similiar_user(liked_book_ids)

    if user_with_same_liked is None:
      raise HTTPException(
        status_code=status.HTTP_404_NOT_FOUND,
        detail="user with similiar liked book not found"
      )

    target_user = user_with_same_liked

  all_books = list({b for books in SVDRecommender.user_items.values() for b in books})
  read_books = set(SVDRecommender.user_items.get(target_user, []))
  unread_books = [b for b in all_books if b not in read_books]

  # Prediksi skor untuk buku yang belum dibaca
  predictions = [
    (book_id, SVDRecommender.svd_model.predict(target_user, book_id).est)
    for book_id in unread_books
  ]

	# Urutkan berdasarkan rating prediksi tertinggi
  top_recommendations = sorted(predictions, key=lambda x: x[1], reverse=True)[:pagination.limit]
  recommended_ids = [b for b, _ in top_recommendations]

  books, total = BookCRUD.get_similiar_books(None, pagination, recommended_ids, db)

return books, totalIntegration With the Frontend
The frontend implementation is relatively straightforward. Its main responsibility is to consume the recommendation APIs provided by the backend and display the returned results to the user. Therefore, instead of discussing the frontend implementation in detail, I will focus on the integration flow and present the final result.
Integrating the Content-Based Filtering Model
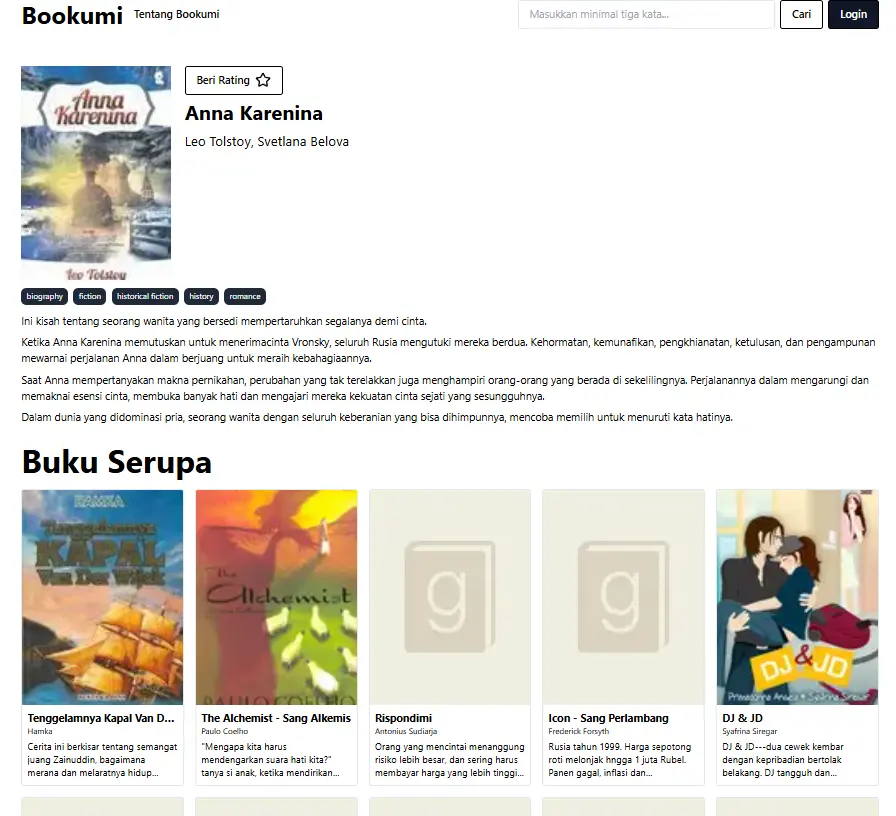
I integrated the content-based filtering model into the book detail page. Since the book detail data already contains the information required to request similar books, the recommendation endpoint can be called directly from this page.
The integration flow is as follows:
- Retrieve the book details.
- Construct the required parameters for the content-based filtering endpoint.
- Send a request to the recommendation endpoint.
- Receive the response and map the recommended books to the book list component for display.
As shown in the “Buku Serupa” section, the displayed list of books is generated by the content-based filtering model. These recommendations represent books with similar content to the selected book.

As shown in the browser's Network panel, the page first sends a request to retrieve the book details. The data returned from this request is then used to construct the parameters for the similar-book endpoint, which retrieves books with similar content based on the selected book.
Integratin the Collaborative Filtering Model
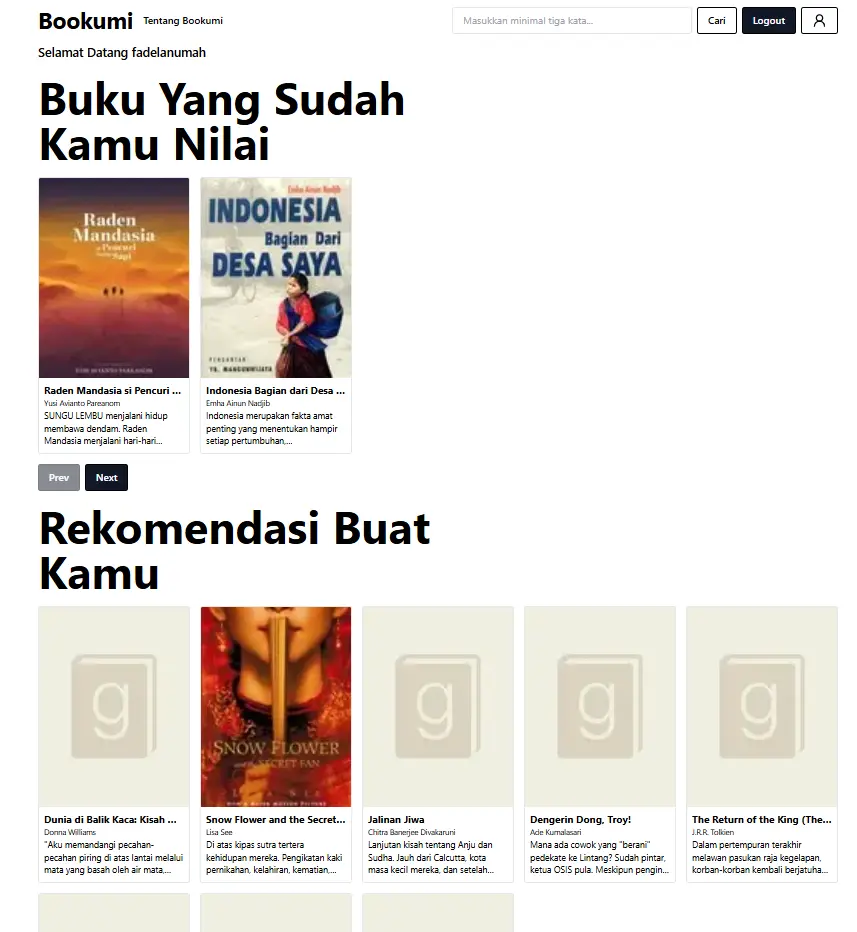
Unlike the content-based filtering model, the collaborative filtering model requires additional supporting features, specifically user authentication and book ratings. The concept is straightforward: users must log in so the system can identify which books they like or rate. This user preference data is then used by the collaborative filtering model to generate personalized recommendations.
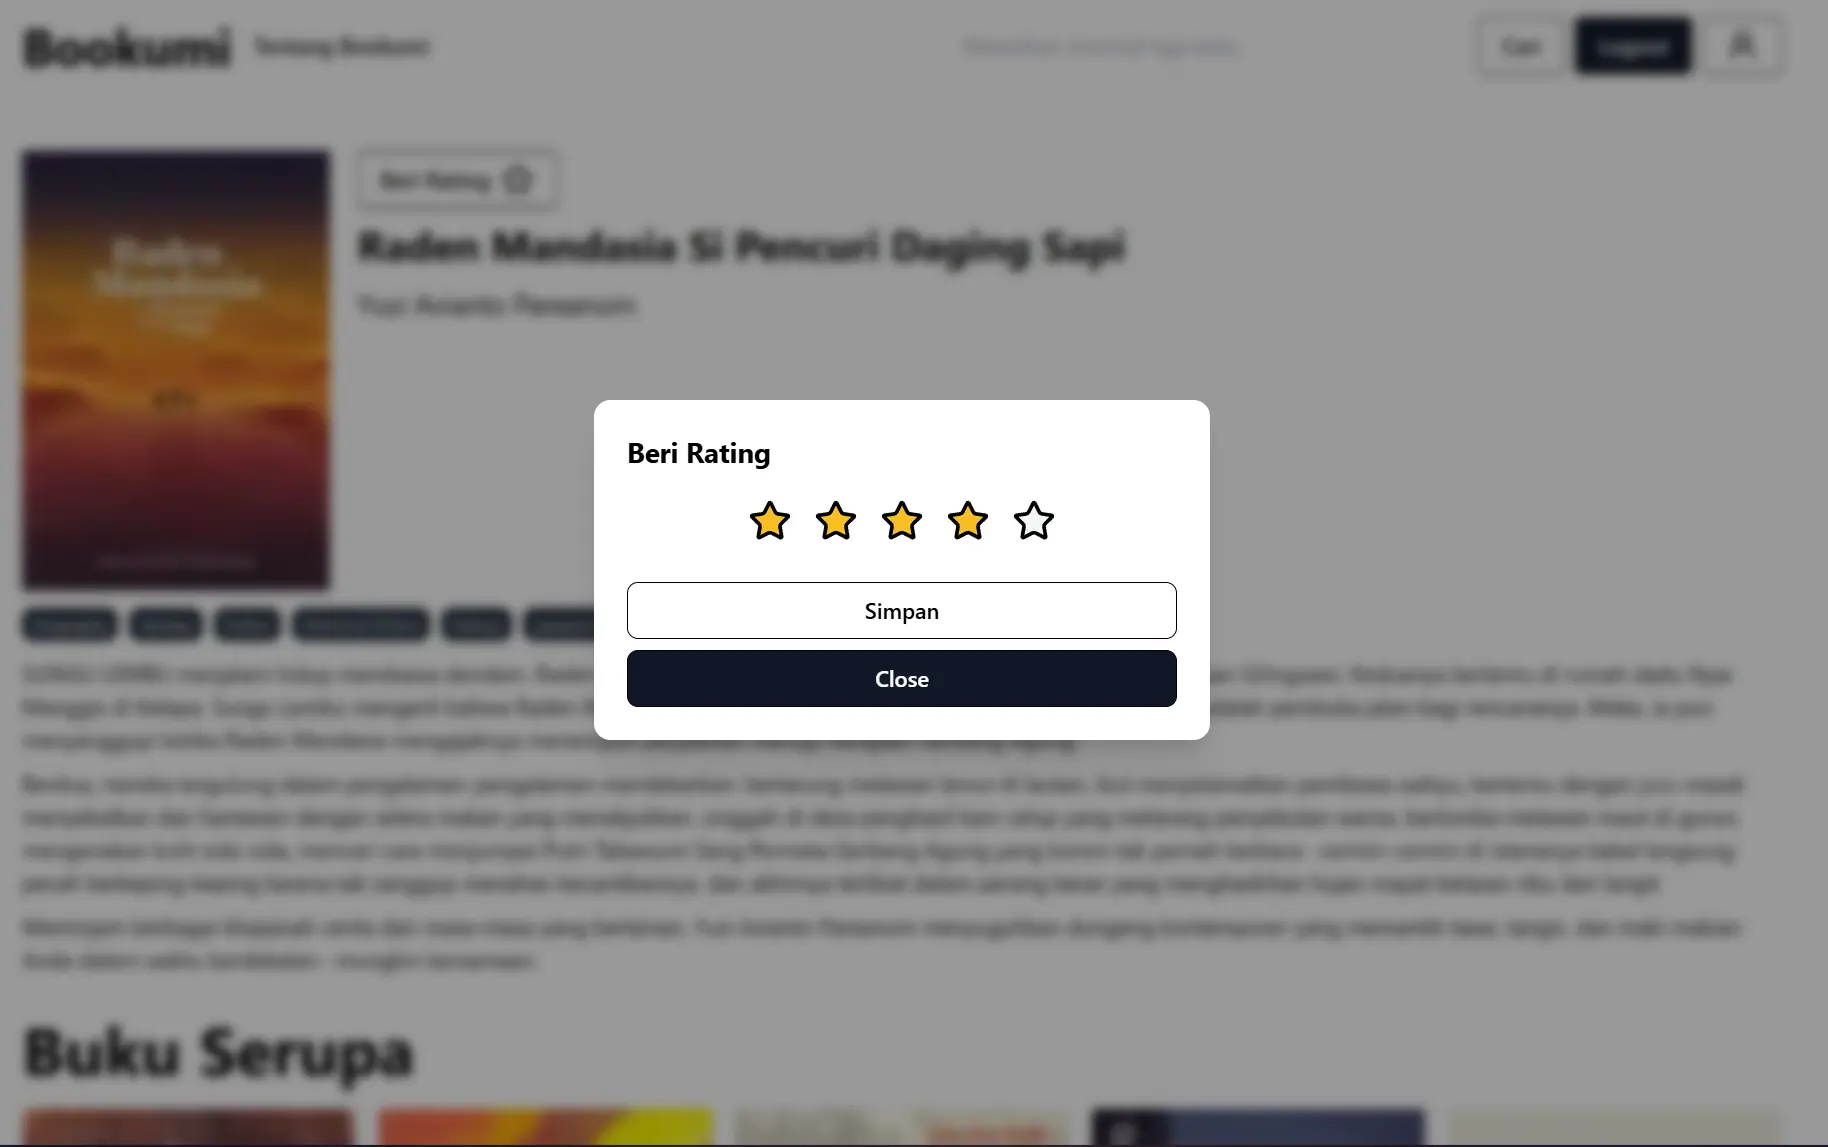
Books that have already been rated by the user are displayed in the “Buku Yang Sudah Kamu Nilai” section on the user's profile. Meanwhile, the recommendations generated by the collaborative filtering model are displayed in the “Rekomendasi Buat Kamu” section.
Closing Statement
This concludes the implementation of my hybrid recommender system and its integration with the website frontend. By integrating the recommendation models into a web application, the system becomes more user-friendly and accessible through an intuitive user interface compared to interacting with the models directly through a terminal.
However, this implementation is not intended to be a perfect or fully optimized recommendation system. The primary focus of this project is to demonstrate how the trained models can be prepared, loaded into a backend service, and served to a frontend application. The quality of the recommendations can be further improved by using a larger and higher-quality dataset, as well as applying more advanced model optimization and tuning techniques.